Project Story
A biological age score built from published research, and checked against it
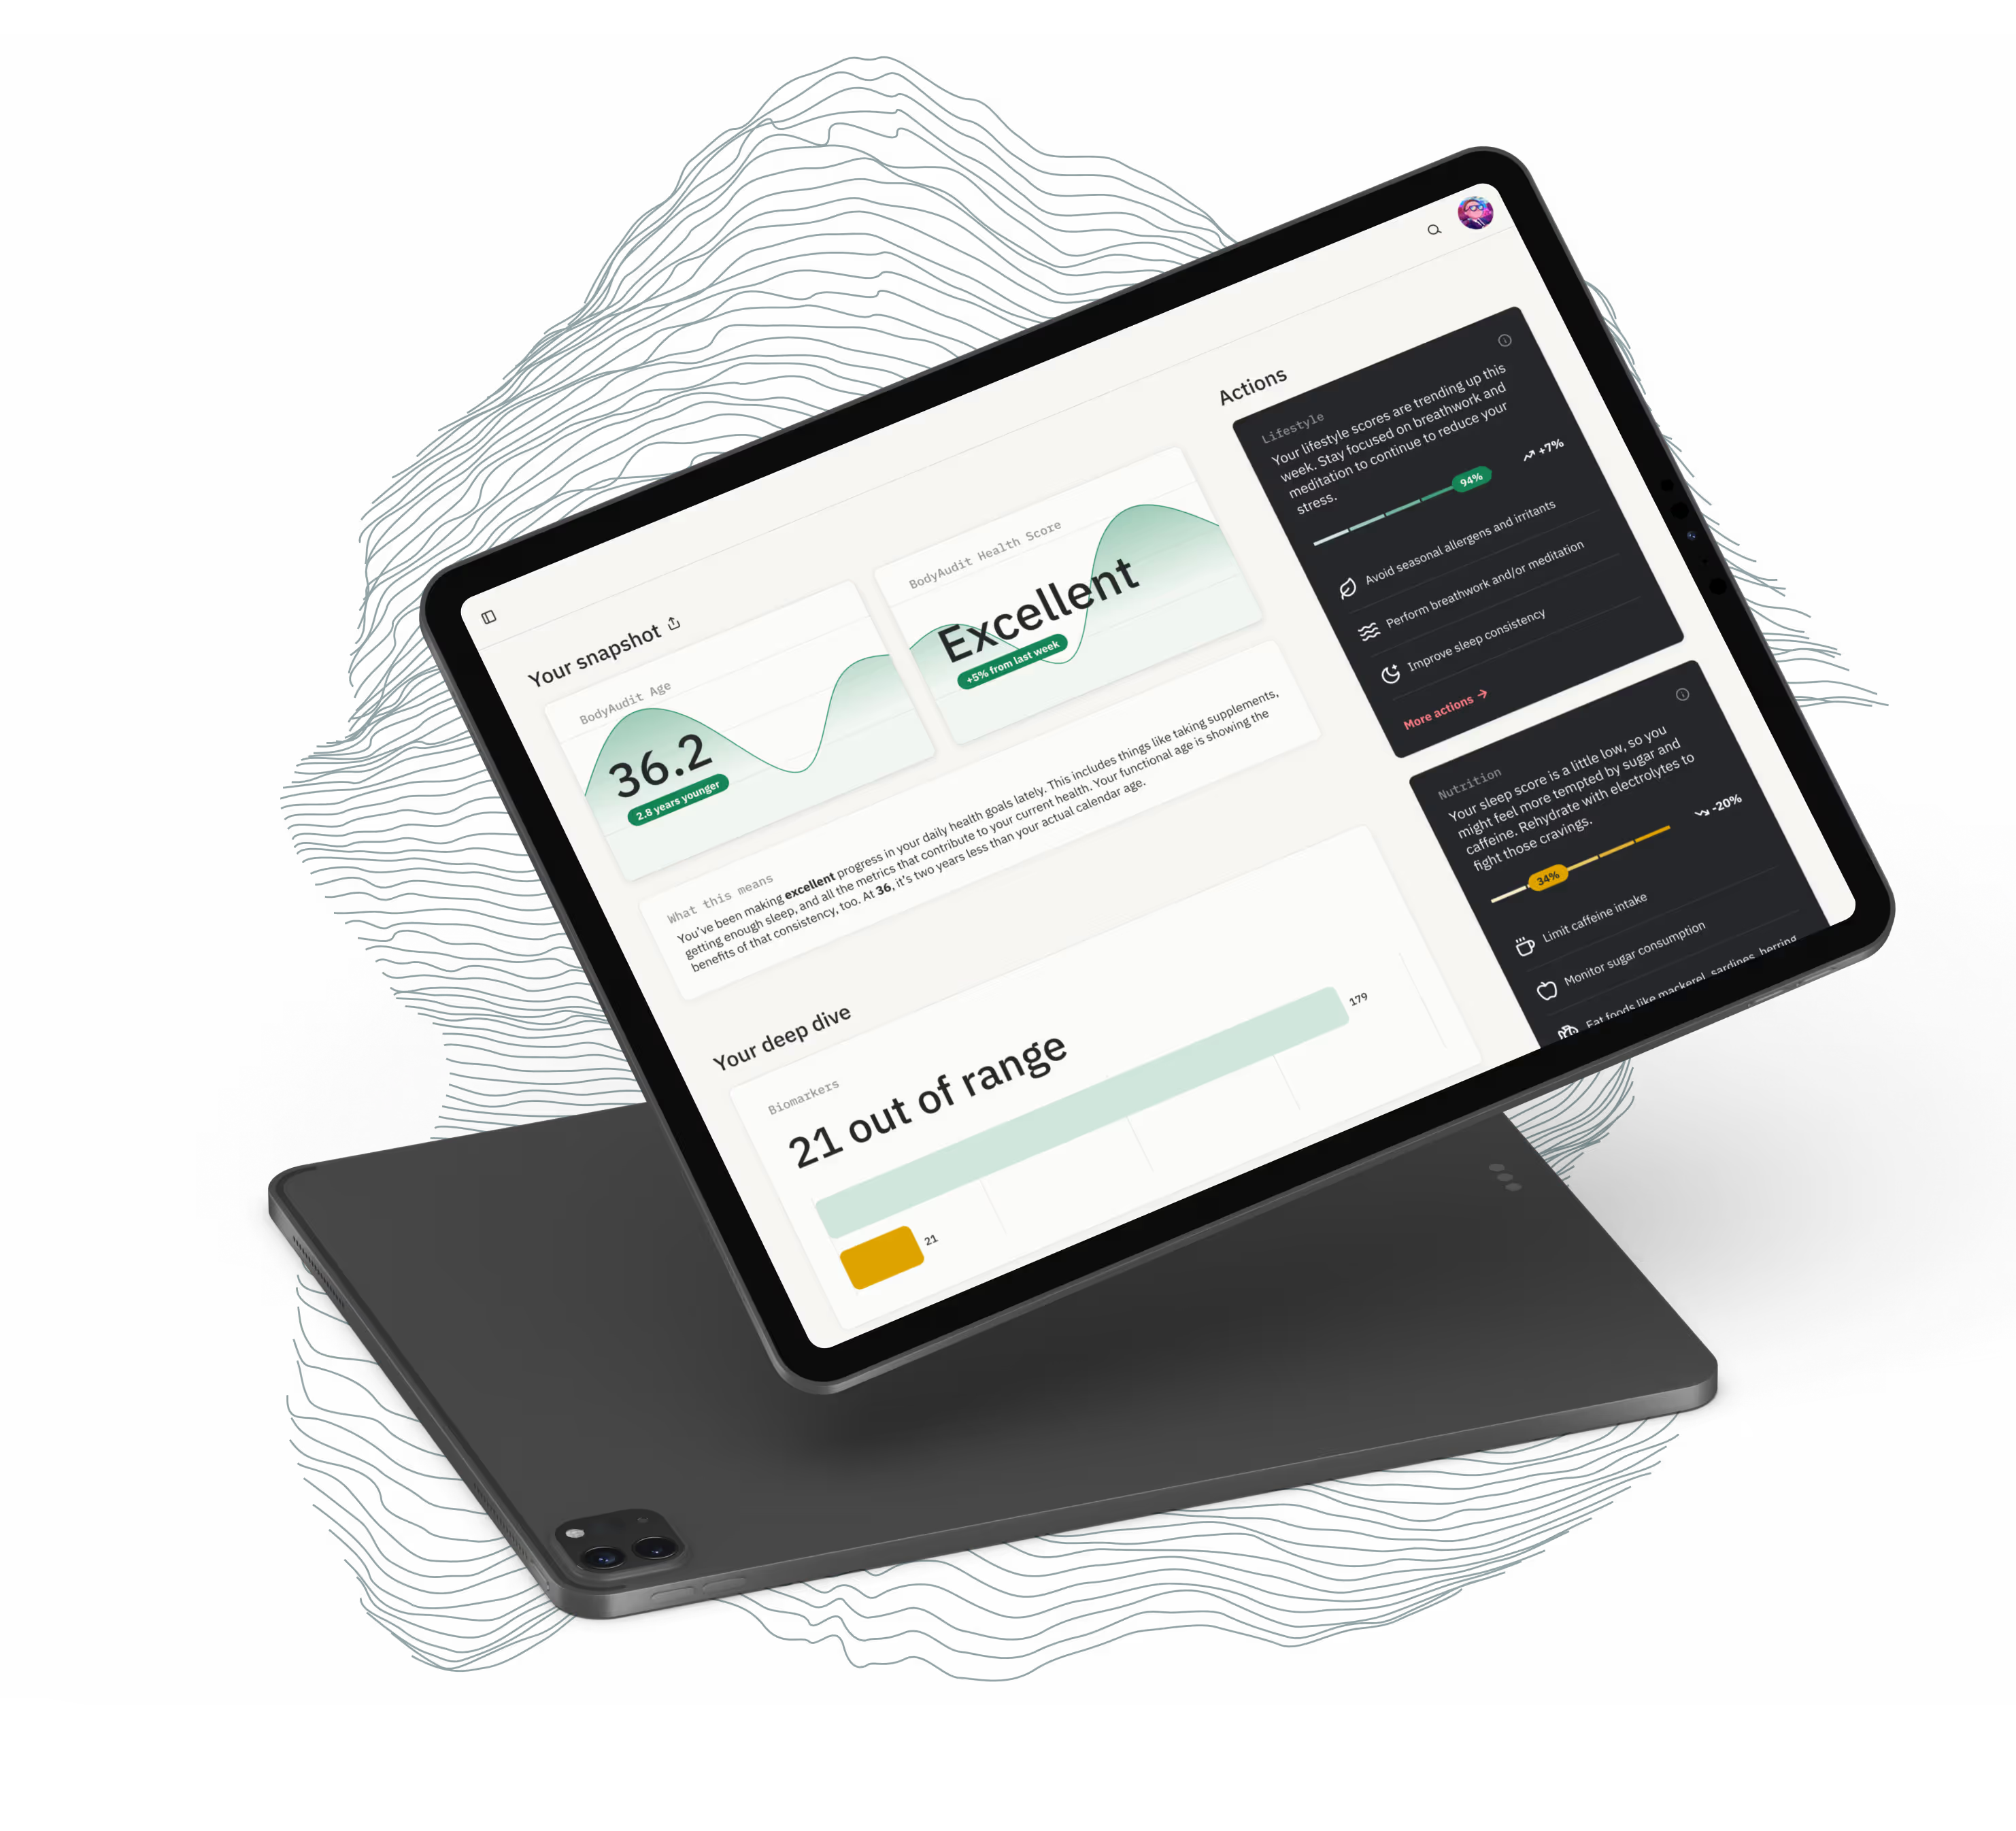
We built the BodyAudit Age score on the Klemera-Doubal method (published in 2006) in TypeScript, with sex-specific parameters, a clamp, confidence levels and every tunable number in one config file, then checked the code against a fully worked example before it shipped. The same lab results drive a Health Score and pick which of 29 actions a subscriber sees.
- Client
- BodyAudit
- Industry
- Preventive health
- When
- 2026
- Status
- Live since August 2026
- Next.js
- TypeScript
- tRPC
- Prisma
- PostgreSQL
- Shopify
- Recharge
What goes into the number
BodyAudit subscribers take a blood sample at home, one panel per renewal, cycling through three panels (Performance, Longevity and Energy). The lab’s results come back through the kit vendor’s API as FHIR observations, and the BodyAudit Age turns them into one estimate of biological age that sits next to the person’s actual age on the dashboard.
We built it on the Klemera-Doubal method (KDM), published in Mechanisms of Ageing and Development in 2006. The model treats some biomarkers as drifting predictably with age. DHEA-S goes down and SHBG goes up, for example. For each one it asks what age would typically produce this value, then blends those answers, giving more say to the markers that track age most tightly. The person’s real age goes in too, as an anchor, so the estimate stays sensible when there isn’t much data.
The male model uses 16 biomarkers and the female model uses 14. We left out markers whose age curve jumps or bends instead of drifting: FSH in women steps up at menopause, SHBG in women follows a U shape, and Lp(a) barely moves with age at all. Those markers still count toward the separate Health Score. Real age comes from the birth year on the account, treated as July 1 of that year, so it’s a fractional age instead of a whole number.
The formula, as code
Each biomarker in the model carries three numbers from a linear regression of that marker on age: an intercept a, a slope b and a residual standard deviation s. A marker’s weight is b² / s², so a steep slope with little scatter counts for a lot and a noisy one counts for little. The estimate is a weighted average of every marker’s implied age plus the person’s real age, and real age carries a fixed weight of 1 / sBA² with sBA set to 11 years.
computeBodyAuditAge is a pure function with no database calls, which is what made it easy to check. The details that matter in practice:
- hs-CRP is spread over a huge range, so the model uses its natural log, with values floored at 0.1 before the log so a result of zero can’t blow up the math.
- The result is clamped to 15 years either side of real age and rounded to one decimal.
- Confidence comes from how many of the model’s markers are present. Fewer than 3 falls back to real age with an
isFallbackflag. 3 to 5 is preliminary, 6 to 11 is moderate and 12 or more is high. - Locked panels (ones the subscriber hasn’t taken yet) are skipped. A few markers, hs-CRP among them, show up on more than one panel, and the most recent value wins.
- With no birth year on file there’s nothing to anchor to, so the function returns a fallback instead of guessing.
With all 14 female markers present, the biomarkers carry 48.3% of the total weight and real age carries 51.7%. That’s deliberately conservative, and it means a single panel can’t swing the number far.
Getting lab values into the formula
The formula is the easy part to describe. Most of the code is in the adapter that turns the lab’s FHIR bundle into numbers the formula can trust.
The lab sends no LOINC codes (the standard IDs for lab tests), so results are matched to our biomarker templates by name. Names are lowercased, stripped of parentheticals, commas and hyphens, then checked against a table of the lab’s own short names (“hs crp”, “dhea s”, “testosterone total”) before falling back to a substring match. After that alias table went in, all three panels matched every analyte the lab returned except GGT, which has no template.
Values arrive as strings. A censored result like “<200” is read as 200, and anything non-numeric (“Negative”, “Not Detected”) is dropped instead of scored. The adapter doesn’t convert incoming units. The regression parameters and reference ranges are written in US conventional units (mg/dL, ng/mL, mcg/dL), so a lab that switched to SI units would need a conversion step first. The free androgen index is defined in SI units, so that one formula converts testosterone from ng/dL to nmol/L (× 0.0347) before dividing by SHBG. The adapter also computes 16 ratio markers from the raw ones, among them AST/ALT, TG/HDL, FT3/FT4 and an eGFR using the race-free CKD-EPI 2021 equation.
Every biomarker also gets its own 0 to 100 score against the reference range stored with its template. A value at the midpoint scores 100 and one at the edge of the range scores 70. Out-of-range values fall from 60 toward a floor of 10 the further out they are. Scores of 80 and up read as optimal, 60 to 79 normal, 40 to 59 at risk and under 40 critical. Those cutoffs drive the Health Score and the actions engine.
How we knew the code matched the formula
A formula from a paper is easy to get subtly wrong in code. A flipped sign or a misplaced log and the output still looks like an age, just the wrong one.
The research document we built from worked one case all the way through: a healthy 45-year-old man with 16 specific values, down to the implied age of each marker. It came out at 41.1. Our code had to produce 41.1 from the same inputs before anything else got built on top of it, and it did. The same document changes three of his values (hs-CRP to 4.0, ApoB to 140, DHEA-S to 120), which lands at 47.0, so we checked that one too.
Those two became the first of six scenarios in testCompositeScores.ts, a script that runs against the real computeCompositeScores function with no database or environment variables:
- one panel only, where the estimate should stay close to real age and be labeled preliminary
- a healthy 38-year-old woman, to confirm the female model gives a different answer than the male one
- an hs-CRP of 15 with everything else healthy, where the Health Score has to land at 49 or lower
- no birth year on file, where it falls back cleanly
In the CRP case, two red-flag rules fire at once: hs-CRP above 10 caps the score at 55, and that marker’s own score of 15 trips the “any marker below 25” rule, which caps at 49. All matching caps apply and the lowest wins.
To be fair about what this is, the script prints each scenario’s output for a person to compare against the expected values. It doesn’t assert. All six came out as expected before the change merged. It’s the first thing to rerun whenever a parameter changes.
One file for every number someone might want to change
Every tunable value lives in src/config/compositeScores.ts: the KDM parameters for both sexes, sBA, the clamp, the confidence thresholds, the Health Score domains and weights, the red-flag rules, the label cutoffs and the staleness decay. The compute file holds only logic. If BodyAudit’s advisors want a weight changed, it’s one line.
The Health Score uses the same biomarker scores. Six domains are weighted Cardiovascular 25%, Inflammation 20%, Hormonal Balance 20%, Metabolic Reserve 15%, Thyroid and Energy 10% and Nutritional Status 10%, with a different hormonal domain for men and women. Domains with no results yet are dropped and the rest are re-weighted to add up. Liver markers act as a modifier: if their combined score falls below 60, Metabolic Reserve loses half the shortfall. Older results fade, at full weight for 3 months, then 90%, 75% and 50%, and they drop out entirely after 12 months. Ten red-flag rules (kidney function, albumin, PSA, thyroid and the CRP rule above among them) cap the final score no matter how good the average looks. Labels are Excellent from 85, Good from 70 and Fair from 50.
How actions get picked
The second half is the actions engine, which replaced the placeholder recommendations the dashboard was designed around. There are 29 actions (10 lifestyle, 10 nutrition and 9 supplements) defined in src/config/actions.ts, and each one lists the biomarkers it targets by LOINC code. Between them they cover 47 of the 51 biomarkers BodyAudit measures.
An action only shows up when at least one marker it targets scores below 60. If any of those markers is below 40, the action is marked high impact. Someone whose results are all in good shape sees an “all clear” screen and no list at all. Each category gets its own score, a weighted average of the markers its actions target, where a marker targeted by four supplement actions counts four times as much as one targeted by one. The “what happened” text on each category is template-built from the three markers whose scores moved most since the last result.
Lp(a), prolactin, bilirubin, LH and FSH (plus the ratios built from them) are on a non-actionable list. When one of those is flagged, the subscriber gets a note to talk with a provider instead of an action. Before launch, every action’s description was checked against the research it cites, and six inaccuracies were corrected.
A subscriber can dismiss an action they don’t want. Dismissals are stored per user and action in a UserActionDismissal table with a unique key on the pair. When new results arrive for a panel, the dismissals for every action that targets a marker on that panel are cleared, so the engine gets a fresh look once the numbers have actually changed.
What it doesn't know yet
The regression parameters were derived from published population figures (NHANES, UK Biobank and other large cohorts) by taking reported means at ages 25 and 75. They weren’t fitted on raw data. BodyAudit’s subscribers are a self-selected group that probably skews younger and healthier than those populations, so the model isn’t tuned to them yet.
The calibration plan is written down. At 2,000 result sets, the parameters get retrained per sex on BodyAudit’s own data with the kdm_calc() function in the BioAge R package, and the config changes if any slope or residual shifts by more than 10%. Before new parameters ship, the clamp should be hit by fewer than 1% of users, and sBA gets a second look. At 10,000 result sets the Health Score label cutoffs can move, by no more than 3 points per cycle.
The score has been live since August 2026, and we don’t have outcome numbers to share yet.
Related case study
BodyAuditQuestions about this project
HQ built the BodyAudit Age score for BodyAudit, a preventive health company that sells at-home biomarker testing. HQ implemented the Klemera-Doubal biological age method, published in 2006, as a pure TypeScript function with sex-specific parameters, checked the code against a fully worked example (a healthy 45-year-old man whose biological age comes out at 41.1), and wrapped it in a six-scenario validation script and a single config file the client can tune.
BodyAudit Age uses the Klemera-Doubal method. For each of 16 biomarkers in men and 14 in women, the formula estimates what age would typically produce that value, then combines those estimates weighted by how reliably each marker tracks age (the regression slope squared over the residual variance), with the person's real age included as an anchor. hs-CRP is log-transformed first. The result is limited to 15 years above or below real age, and its confidence label depends on how many of the model's markers are present, from preliminary at 3 to 5 markers up to high at 12 or more.
HQ ran the code against a worked example from the research the formula was built from, a healthy 45-year-old man whose biological age should come out at 41.1, and the code matched it. A second version of the same man with three worse values should land at 47.0, and it did. HQ then added four more scenarios to a validation script that runs against the scoring code, covering a single panel, a female model, a red-flag cap and a missing birth year.
The lab behind BodyAudit's kits returns FHIR results without LOINC codes, so HQ's adapter matches them to biomarker templates by name. It lowercases each name, strips parentheticals, commas and hyphens, checks a table of the lab's own short names, and falls back to a substring match. With that in place, all three BodyAudit panels matched every returned analyte except GGT, which has no template.
The engine holds 29 actions across lifestyle, nutrition and supplements, each tied to specific biomarkers by LOINC code, covering 47 of the 51 biomarkers BodyAudit measures. An action only appears when a biomarker it targets scores below 60 out of 100, and it's marked high impact if any targeted marker is below 40. Biomarkers on a non-actionable list, such as Lp(a) and prolactin, show a note to talk with a provider instead. Dismissed actions come back when new results arrive for a panel that includes one of their targeted markers.
Let's build together
Whether you're looking to design, build, update, or refresh an existing app or website, we can help. Even if we're not a good fit, we will help point you to somebody who might be.
Contact us